 ObjectExplorer
Query three thousand date folders?
One prefix, one table.
A report had read the wrong days, and I needed to see the data for two of them. The data lived under a prefix three levels deep: year equals, month equals, day equals, one folder per day, going back years. About three thousand folders. I clicked through them in the console.
Today
The console showed the first page of the listing, a thousand entries, and a button for the next. I paged to the right year, then the right month, then opened the day folders one at a time and looked at the file sizes to guess which days had been written properly. When the month rolled over while I was doing this, the folder I cared about moved to a different page.
Then I listed the two days from the terminal to get their full paths, and loaded those files into a notebook to actually read the rows.
- Cloud consoleyear, month, day
- Cloud consolenext page, next page
- Cloud consolecompare file sizes
- Terminallist the prefix
- Notebookload two days
Nothing misbehaved. The console lists a prefix a page at a time because that is how every one of these clouds lists objects: S3 and Google hand back at most a thousand keys per request. The terminal listed what I asked for. The shared assumption was that three thousand folders are three thousand things, to be walked one at a time.
Ideal
So I asked why there were three thousand folders. Because whoever wrote the data wrote a day at a time, and put each day in its own folder so that a reader could skip the days it doesn't want. They never meant three thousand things. It was one table the whole time, and the folder names are a column in it. That is what "year=2024" says: a column called year, with the value 2024, for every row underneath.
If that is true, then the folder at the top is the table, and opening it should show rows, not a listing. Asking for two days should be a filter on a column, not a hunt through pages. And the layout on disk only matters for making the filter cheap.
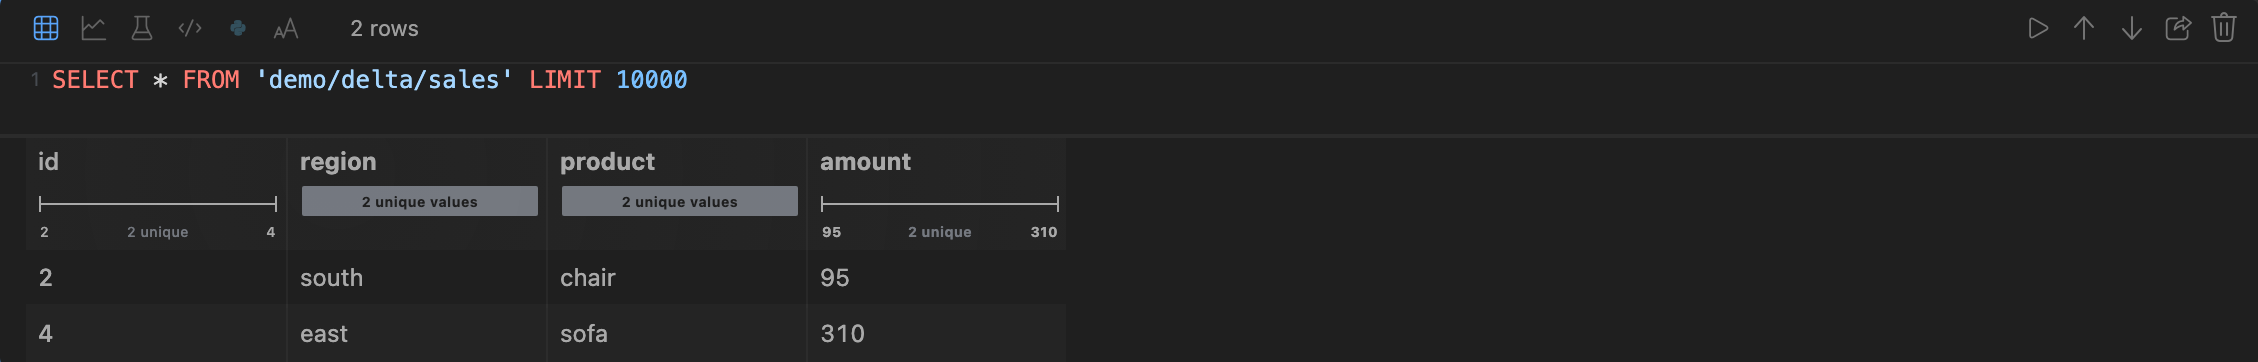
That picture is the same idea on a smaller table: a folder, named by its path in a query, answering as one table with a summary over every column. In the code, a folder where every child is named key=value is recognised as a partitioned table and opens as one, with every data file under it read together and the partition names turned into columns. A layout of bare dates, like 2026/08/10, gets year, month and day columns cut out of each file's path, and the query that does it is written out in full so it can be edited. Listings page themselves: the next thousand arrive as I scroll.
Where it stops
The cheap filter is not something I can promise yet. The query the table opens with reads the whole prefix, up to 10,000 rows, and before it runs, everything under the prefix is listed. If I narrow the path in the query to one month, only that month is listed. But a filter on the day column is left to the query engine, and I haven't verified that it skips the other days' files rather than fetching them. Every file the engine does open is downloaded whole to a local cache first.
So "one prefix, one table" is built. "Only those folders get touched" is only true when I say the folders in the path.
One prefix, one table.