 ObjectExplorer
Models
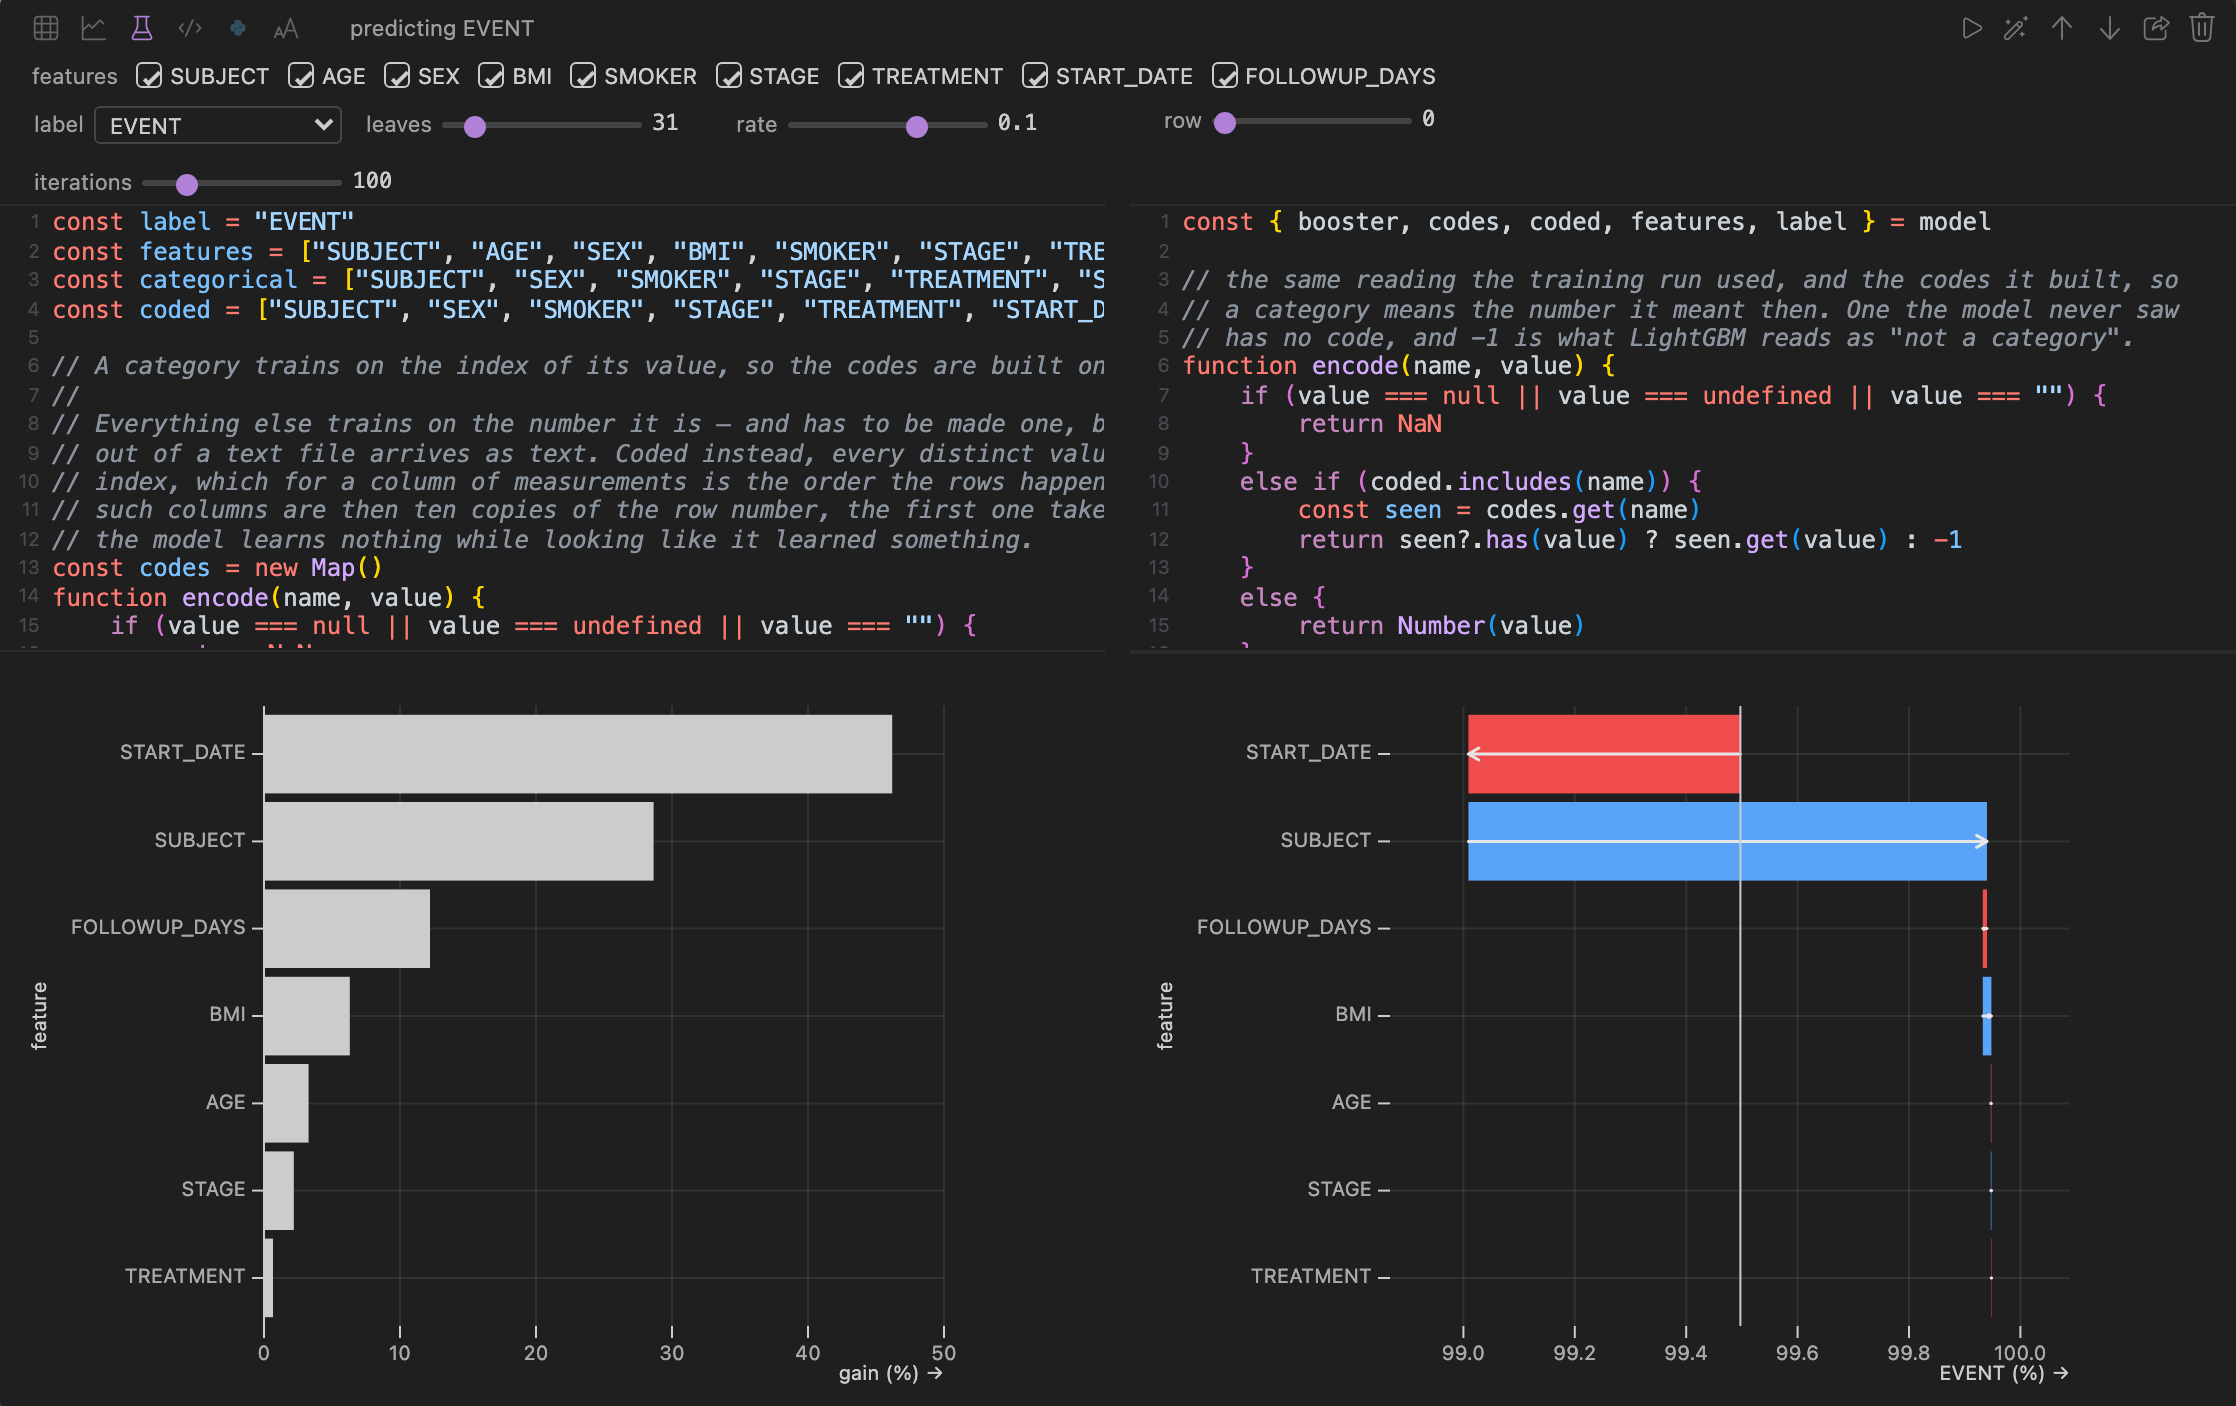
A model cell is gradient boosting — LightGBM's algorithm, built into the app — over the rows the cell above produced.
Pick the label, the column you want predicted, and the rest comes from the same statistics the grid already drew: whether the question is which one or how much, which columns are worth training on, and which are row numbers that would teach the model the order the file was written in and nothing else. The other columns are chips you can click out of the features. Rows with no label are left out of the training.
The controls hide nothing
Leaves, rate and iterations are three sliders, and moving one prints the JavaScript underneath it — that printed source is what trains when you run the cell, so a slider and a hand edit end in the same place.
The two plots
The first plot draws what the model learned: the features ranked by their share of the total gain.
The second answers the other question — drag the row slider, and a waterfall walks from what the model says on average to what it said about that one row, feature by feature. Those contributions are TreeSHAP, exact and additive, so the steps add up to the prediction rather than approximating it.
Both plots show the same features in the same order, so the pair reads across: what a column is worth over the whole file, and what it did to this row.
It all runs where the data already is. A model over a bucket you are not allowed to copy out of is still just a local read — and the copy button in the cell's toolbar puts the model on the clipboard as LightGBM's model.txt, which lgb.Booster(model_str=…) loads, without a single training row going with it.
Next: data lake tables.